Hive to Microsoft Fabric Lakehouse Migration Accelerator: A Step-by-Step Case Study
 0|
 0
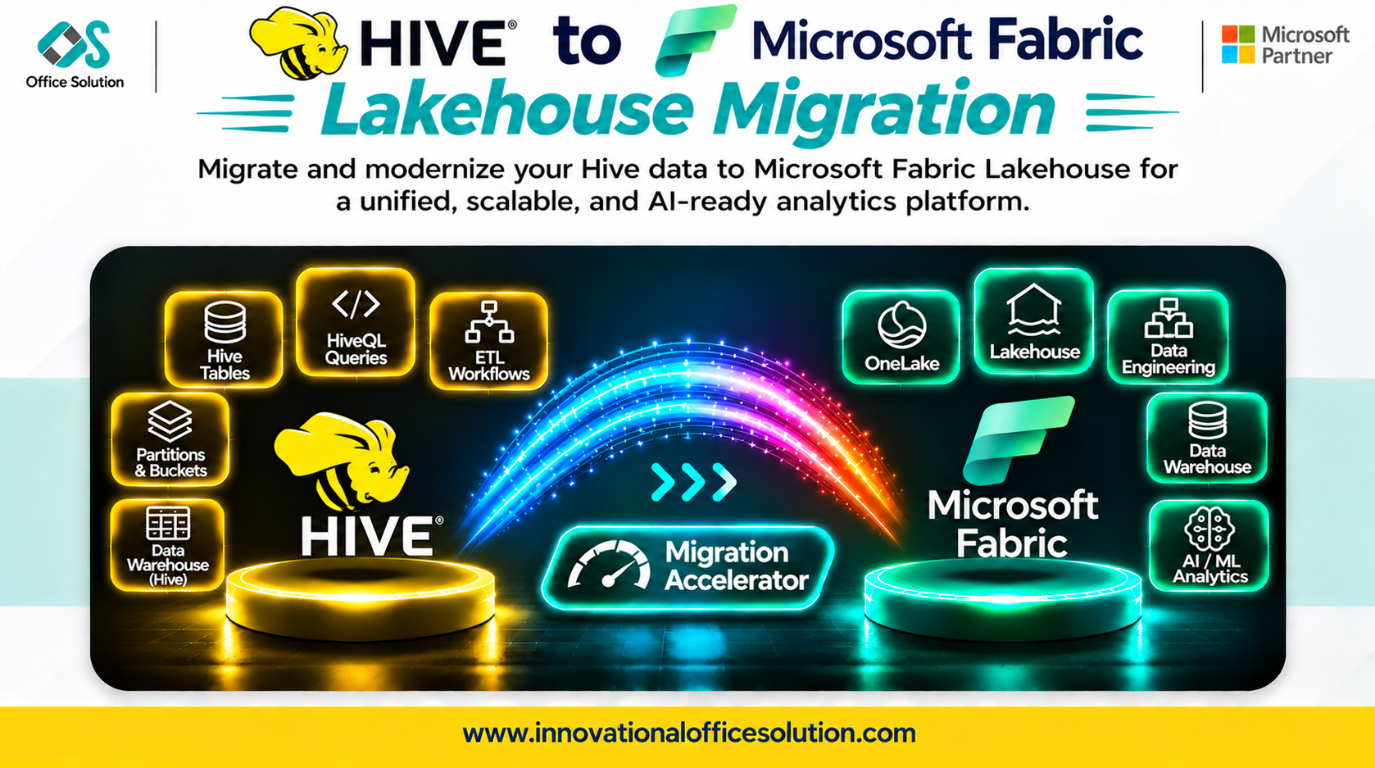
Table of Contents
Hive to Microsoft Fabric Lakehouse Migration Accelerator: A Step-by-Step Case Study
Client profile: Enterprise data teams running Apache Hive on Hadoop clusters and seeking modernization on Microsoft Fabric Lakehouse.
Solution: Pulse Convert Hive to Fabric Lakehouse Accelerator by Office Solution AI Labs.
Automated accuracy claim: 70–90% of schema and HiveQL or ETL code can be converted automatically, with the remainder requiring expert fine-tuning and validation.
Executive Summary
Moving from Hive to Microsoft Fabric Lakehouse is more than a storage swap. Hive's partition-centric model, HiveQL dialect, SerDe formats, and external table patterns have no one-to-one Lakehouse equivalents. Teams that treat this as copying data and pointing Power BI at it can encounter broken partitioning, schema drift, and incomplete query results.
This case study describes a practical migration process, the challenges that derail projects, and how Pulse Convert accelerates repeatable work so engineers can focus on complex, high-judgment edge cases.
Step-by-Step Migration Process
Step 1: Discovery and Inventory (Weeks 1–2)
Extract metadata from the Hive Metastore to inventory databases, managed and external tables, partition schemes, views, UDFs, and HiveQL or Spark jobs.
- Key output: A migration backlog prioritized by business value rather than table count.
- Flag stale or unused tables for retirement instead of migration.
- Critical check: Document managed versus external tables, storage formats such as ORC, Parquet, Avro, and Text, SerDes, and partition strategies.
Step 2: Target Architecture Design (Week 2)
| Hive workload | Fabric target |
|---|---|
| Managed internal tables | Lakehouse Delta tables |
| External tables | Lakehouse shortcuts or OneLake references |
| Partitioned tables | Delta partitioning on equivalent keys |
| HiveQL batch jobs | Fabric notebooks using Spark SQL or PySpark |
| Hive views | Lakehouse views or Spark SQL views |
| Java or Python UDFs | PySpark or Python UDFs |
| Reporting queries | Power BI Direct Lake or SQL endpoint |
Fabric runs on capacity units (CUs). Design workspace and capacity allocation early to avoid throttling after cutover.
Step 3: Schema and Code Conversion (Weeks 3–8)
Convert DDL first, then HiveQL jobs, and finally orchestration.
- HiveQL dialect: Translate functions such as LATERAL VIEW explode, collect_list, get_json_object, and nvl into Spark SQL or PySpark equivalents.
- Partitioning and small files: Compact partitions with OPTIMIZE and use ZORDER where it improves query performance.
- ACID tables: Recreate transactional semantics as Delta tables using merge logic rather than carrying bucket metadata forward.
- Data type drift: Replace Hive implicit casts and loose STRING usage with enforced Delta schemas.
- Case sensitivity: Standardize column casing because Hive is commonly case-insensitive while Spark and Delta are case-sensitive.
- SerDes and custom formats: Replace non-standard SerDes with native Spark readers.
- Validation: Every converted object must be checked against the source rather than assumed correct.
Step 4: Validation and Reconciliation (Weeks 9–10)
Run parallel queries to compare row counts, partition-level aggregates, and business KPIs between Hive and Fabric. Automate reconciliation, including partition boundaries and null or cast behavior.
Step 5: Cutover and Decommission (Weeks 11–12)
Use phased cutover by subject area and keep Hive read-only during the transition window. Track Hadoop cluster and license retirement as a formal cost-saving milestone.
Key Challenges in Hive-to-Fabric Lakehouse Migration
| Challenge | Why it matters | Mitigation |
|---|---|---|
| HiveQL dialect gaps | Some functions behave differently in Spark SQL. | Test each function and rewrite where needed. |
| Small-file problem | Thousands of files per partition can collapse performance. | Compact with OPTIMIZE and ZORDER. |
| ACID to Delta | Transactional semantics do not carry over directly. | Recreate as Delta tables with merge logic. |
| Loose typing and schema drift | Delta enforces schema and can reject implicit casts. | Enforce explicit schemas and validate casts. |
| Case sensitivity | Hive and Spark can disagree on column casing. | Standardize column casing during conversion. |
| Partition design | Wrong keys cause over-partitioning or skew. | Review partition strategy before load. |
| SerDe formats | Custom SerDes need native Spark readers. | Rewrite ingestion for non-standard formats. |
| Fabric capacity planning | CU throttling affects performance. | Size capacity and workspaces before cutover. |
How Pulse Convert Accelerates the Journey
Pulse Convert Hive to Fabric Lakehouse Accelerator targets high-effort, repeatable work: bulk DDL translation, standard HiveQL conversion, and automated inventory analysis.
What It Does Well
- Automates 70–90% of schema and repeatable HiveQL or ETL code conversion.
- Reduces manual translation effort on bulk objects.
- Generates a conversion inventory with complexity flags for review prioritization.
What Still Needs Humans
- Complex Java or Python UDFs.
- ACID table redesign.
- Small-file compaction strategy.
- Business logic validation and source-to-target reconciliation.
No tool migrates every Hive object perfectly. Pulse Convert automates repeatable bulk work and routes difficult cases to engineers; accuracy is validated against the Hive source.
Next Step: Free POC
See Pulse Convert on your Hive workload. We can migrate a representative sample to Microsoft Fabric Lakehouse, validate it against your source, and demonstrate accuracy before you commit.
- Contact: Admin@innovationalofficesolution.com
- Free POC offer: Request a migration proof of concept
- Website: Innovational Office Solution
- Office Solution AI Labs — Microsoft Solution Partner


